

The Data Is Out There… and Someone’s Scraping It
In 2025, data isn’t just “the new oil.” It’s the bloodstream of the modern digital economy—and web scraping is how that data moves.
Once a niche skill used by coders and curious tinkerers, web scraping has become a mainstream business operation. From price monitoring and sentiment tracking to training AI models, data extraction has quietly become one of the most valuable (and controversial) parts of the internet’s infrastructure.
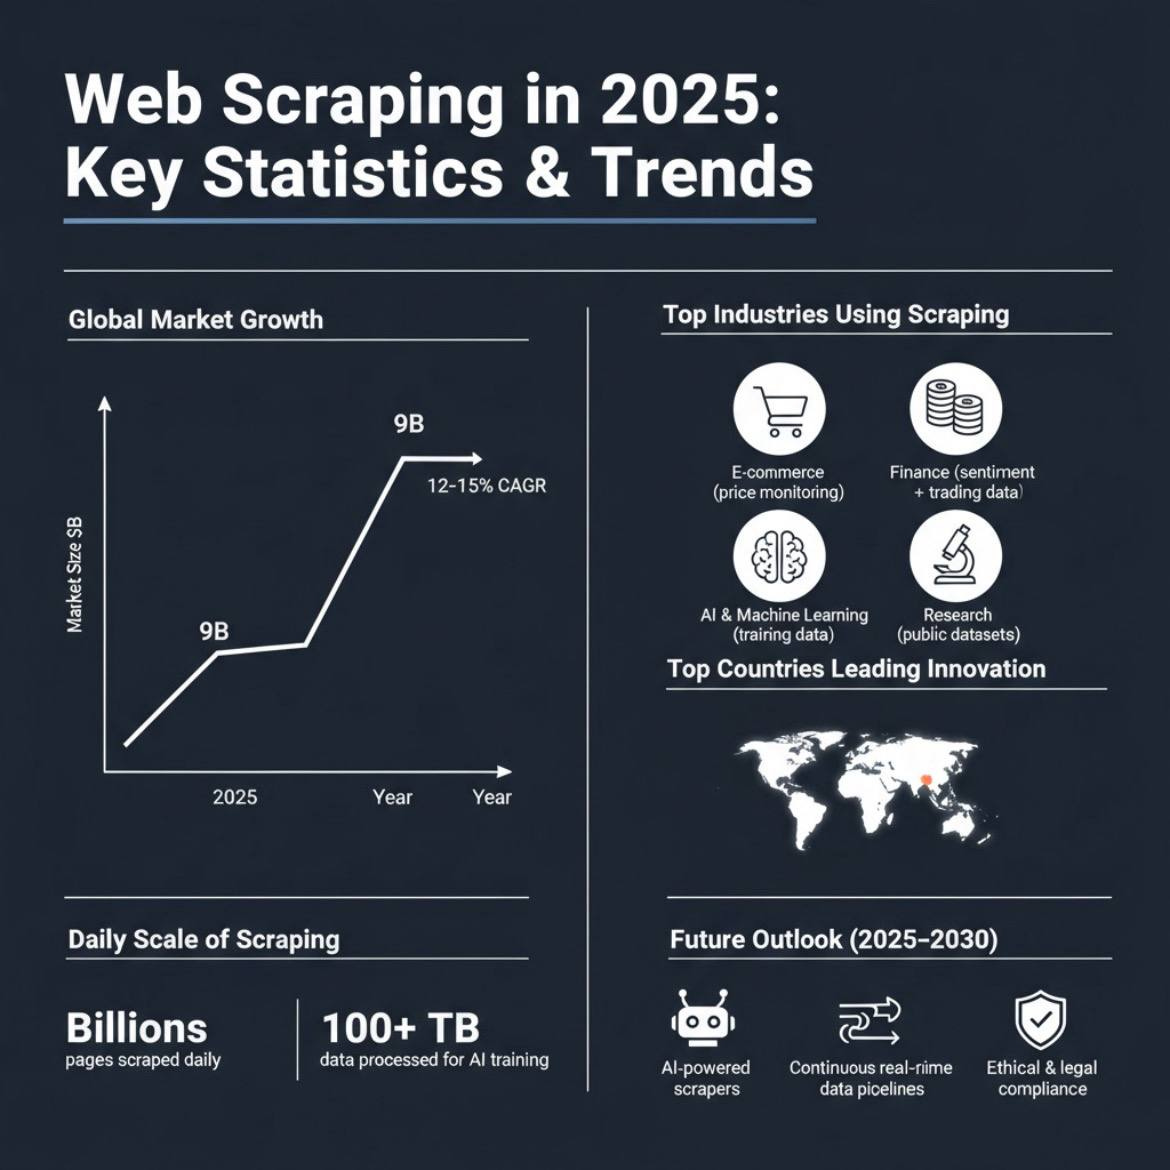
Web scraping is now woven into how companies operate. E-commerce players rely on it for real-time market intelligence, financial firms for predictive modeling, and AI developers for training massive machine learning systems. What was once a hacker’s hobby is now a $9-billion industry.
Let’s dive into the statistics and trends defining web scraping in 2025—and how it’s reshaping the way businesses compete, innovate, and stay informed.
The Global Web Scraping Market Tops $9 Billion
According to multiple industry analyses, the global web scraping market will exceed $9 billion in 2025, growing at an estimated 12–15% CAGR through 2030.
That figure reflects a clear shift: scraping isn’t a side project anymore; it’s a recognized operational expense.
What’s fueling the surge:
E-commerce competition: Companies scrape millions of listings daily to track prices, availability, and reviews.
AI & machine learning: Scraped data provides diverse, high-volume input for training generative models and recommendation systems.
Low-code tools: Platforms like Octoparse and ParseHub have democratized scraping—anyone can set up data pipelines without writing code.
Cloud automation: Distributed scraping setups running across proxies now collect data at scale with minimal manual effort.
In short: the world’s data is being extracted, structured, and sold faster than ever—and that momentum shows no signs of slowing down.
Who’s Doing the Most Scraping
Some industries don’t just use web scraping—they depend on it.
E-commerce
Over 80% of top online retailers scrape competitor sites daily to adjust pricing and track product performance. What was once manual “price checking” is now automated in real time.
Finance
Roughly 60% of hedge funds and investment firms use scraping to track sentiment, filings, and news signals before making trades. For them, faster data means a measurable trading advantage.
Artificial Intelligence
An estimated 70% of large AI models rely on scraped data—from text and product metadata to public images and forums. Without scraping, today’s AI systems would simply run out of training fuel.
Research & Academia
Public health, climate science, and social research projects increasingly depend on automated data collection from open portals and government sites.
Other emerging users include travel agencies, sports analytics startups, and even hospitality companies scraping competitors’ rates and customer reviews.
How Much Data Is Being Scraped
The scale of scraping in 2025 is staggering.
What once measured in gigabytes is now terabytes or even petabytes per day.
Billions of pages scraped daily worldwide
Millions of products tracked by e-commerce scrapers
Hundreds of millions of sentiment data points processed by financial algorithms
Over 100 TB of scraped data feeding AI model training per cycle
Advancements in distributed infrastructure, proxy rotation, and AI-driven parsing allow scrapers to run continuously with minimal downtime.
In practical terms: the web has become a 24/7, self-updating data feed—and everyone with the right tools is plugged in.
The Top 5 Countries Leading Web Scraping Innovation
United States – Dominates commercial scraping via massive cloud infrastructure and data-centric enterprises.
United Kingdom – Financial services and academic research drive most scraping activity.
Israel – Leads in stealth scraping tech, AI-assisted data collection, and analytics automation.
Switzerland – Focuses on high-compliance scraping for finance and pharma sectors.
United Arab Emirates – Rapidly growing data hub for travel, logistics, and fintech analytics.
These countries share common traits: advanced data laws, robust cloud networks, and a workforce skilled in automation and analytics.
Scraping as a Core Competitive Intelligence Tool
In 2025, scraping has become the fastest route to business intelligence.
Recent surveys show that:
72% of mid-to-large companies use scraping for competitor monitoring.
85% of e-commerce businesses track rival pricing through automated tools.
60% of marketing teams scrape social media and news for brand and sentiment insights.
40% of B2B SaaS companies use scraped data for lead generation and sales targeting.
What once took analysts days to research can now be automated in minutes—allowing businesses to react in near real time to shifts in pricing, messaging, or market demand.
How Scraped Data Fuels the AI Boom
Artificial intelligence runs on data, and much of that data comes from scraping.
Analysts estimate that 70–80% of public AI training datasets include scraped content—whether from open knowledge bases, product pages, or user-generated forums.
Scraped data fuels:
LLMs (language models) with trillions of web-sourced tokens
Vision models with scraped and labeled images
Recommendation engines with aggregated product and behavior metadata
The takeaway: scraping and AI are now symbiotic.
Scraping feeds AI, and AI, in turn, makes scraping smarter—able to parse dynamic pages, detect content changes, and adapt automatically.
The 2025 Tech Stack: What Scrapers Are Built On
Web scraping today blends traditional and modern technologies:
Frameworks: Scrapy, BeautifulSoup, Playwright, Puppeteer
Proxy Networks: Residential and mobile proxies from providers like Bright Data, Smartproxy, and Oxylabs
No-Code Tools: Octoparse, ParseHub, Import.io
Cloud Orchestration: Serverless deployments and distributed job schedulers for scalability
AI-Driven Adaptation: Systems that detect layout changes and self-correct parsing logic
The biggest shift of 2025: scraping is moving from scripts to systems.
Automation, monitoring, and self-healing architecture are now the norm.
Risks, Rules, and the Gray Zone
Despite its ubiquity, scraping still sits in a legal and ethical gray area.
The challenges include:
Anti-scraping defenses: CAPTCHAs, fingerprinting, and behavioral detection
IP bans: Over-aggressive scraping can trigger blacklists
Legal boundaries: Sites’ terms of service and privacy laws vary widely
Data quality issues: Unstructured or inconsistent pages can distort analysis
Reputation risk: Poorly executed scraping can damage brand credibility
As governments refine digital data laws, compliance-first scraping is becoming essential. Respecting robots.txt, throttling requests, and sourcing public data responsibly are now best practices—not afterthoughts.
Where Web Scraping Goes Next
The next five years will push scraping beyond automation into intelligent data operations. Expect to see:
AI-native scrapers that clean and analyze as they collect
Continuous data streams replacing batch scraping
Decentralized scraping networks inspired by blockchain
Tighter regulations emphasizing ethical, transparent data sourcing
In short: web scraping will evolve from data collection to data intelligence—where extraction, enrichment, and insight happen in one pipeline.
Conclusion
In 2025, web scraping has matured into a foundational layer of the data economy.
It drives decisions, feeds AI, and gives companies an edge in markets that move faster than ever.
Businesses that scrape responsibly, automate intelligently, and adapt quickly will thrive in the coming decade.
Those that don’t? They’ll be operating in the dark while their competitors see everything in real time.
In a world overflowing with data, the winners aren’t those who have access to it—
they’re the ones who know how to scrape it, clean it, and act on it before anyone else.
Fascinating. Thank you for this; it realy highlights how crucial data extraction is for advancing AI models.